GPT-6.1 Sol vs Astra: how to run a cost-controlled AI agent pilot
A practical GPT-6.1 Sol vs Astra pilot for lean teams that need to measure output quality, total cost, permissions, review effort, and rollback before scaling agents.
OpenAI released GPT-6.1 Sol on September 29, 2026 as a lower-cost option for complex coding, computer-use, and professional workflows. The company says the model approaches GPT-6 Astra on several of its evaluations while charging lower standard input and output token prices. The API model also supports tool use through the Responses API, and OpenAI lists multi-agent orchestration as a beta capability.
That makes GPT-6.1 Sol interesting for lean marketing, agency, and creator-business teams, but it does not make a model switch automatic. Token prices are only one line in an agent’s cost. A useful decision must include output quality, retries, tool calls, review time, permission failures, and the cost of correcting a bad action. The safest response to the launch is a bounded pilot with a frozen benchmark and a clear rollback.
Table of contents
- What OpenAI changed with GPT-6.1 Sol
- Why this matters: cost changes the agent design
- GPT-6.1 Sol vs Astra: the decision matrix
- Scope one bounded AI agent pilot
- Run the 7-step cost-controlled pilot
- Measure quality, cost, and permission errors
- Stop rules and the rollout decision
- FAQ
- Sources
- Related Resources
What OpenAI changed with GPT-6.1 Sol
OpenAI describes GPT-6.1 Sol as an upgrade to GPT-6 Sol for complex everyday work. Its launch post highlights coding, document-heavy professional tasks, multi-step business workflows, computer use, scientific work, and factuality. Those performance statements come from OpenAI’s evaluations and should be read as vendor evidence, not as proof that every production workflow will behave the same way.
The published standard API prices are $2 per million input tokens, $0.10 per million cached input tokens, $2.50 per million cache-write tokens, and $10 per million output tokens. OpenAI’s model page lists a 1,050,000-token context window, a 128,000-token maximum output, text and image input, and an April 30, 2026 knowledge cutoff. Prompts above 272,000 input tokens use higher rates, and tool-specific charges may apply.
For tool calling, OpenAI directs developers to the Responses API. The model page lists web search, file search, image generation, code interpreter, hosted shell, apply patch, skills, computer use, MCP, and tool search as supported tools. The September changelog also says multi-agent support is available in beta, allowing a root agent to delegate independent work to subagents and synthesize the results.
Availability is broader than a developer-only preview: OpenAI says GPT-6.1 Sol is available in ChatGPT Work and Codex for eligible paid plans, and through the API as gpt-6.1-sol. Availability, quotas, data-residency options, and processing tiers can differ, so teams should verify the current product page before committing a workflow.
Why this matters: cost changes the agent design
A cheaper capable model can change which tasks are practical to automate. A team may be able to keep more context cached, run a second verification pass, compare two drafts, or delegate independent research without spending the entire budget on one attempt. But lower token rates can also encourage unnecessary context, too many agents, and repeated tool calls that erase the expected savings.
Measure the cost of a completed, accepted outcome—not the advertised price of one token. If Sol needs three retries and more human correction than Astra, the cheaper request can become the more expensive workflow. If both models pass the same acceptance test, Sol may free budget for better evidence, monitoring, or distribution.
The multi-agent beta sharpens this tradeoff. OpenAI’s guidance says delegation works best when tasks can be split into independent, bounded workstreams. It can be inefficient when steps depend on one ordered chain, agents compete over shared mutable state, or one slow external operation dominates the run. A lean team should therefore start with an agent graph that is small enough to explain on one page.
GPT-6.1 Sol vs Astra: the decision matrix
Do not frame the choice as “cheap model versus smart model.” Use the task’s risk and evidence requirements. Astra may remain the better control for the hardest reasoning or highest-stakes work. GPT-6.1 Sol may be the better default when it clears the same acceptance bar with lower total cost and predictable review effort.
| Decision factor | Test with GPT-6.1 Sol | Keep Astra as control when |
|---|---|---|
| Task shape | Repeatable, bounded workflow with clear inputs and outputs | The task is ambiguous, novel, or difficult to score |
| Tools | Known tools, narrow permissions, and reversible actions | The run crosses sensitive systems or needs broad judgment |
| Quality | Sol passes the same rubric and evidence checks | Small quality gaps create material customer or brand risk |
| Cost | Total accepted-run cost falls after retries and review | Retries, long outputs, or tool calls cancel the token savings |
| Parallelism | Subtasks are independent and results can be reconciled | Agents would write to the same state or duplicate work |
| Fallback | A failed run can be stopped, reviewed, and rerouted | There is no safe rollback or human approval point |
This matrix supports a complement strategy. Use Sol for research, structured extraction, content QA, and bounded production tasks that pass a rubric. Escalate the unusual cases to Astra or a human specialist. The goal is not to replace judgment; it is to spend the highest level of judgment where it changes the outcome.
Scope one bounded AI agent pilot
Choose a workflow with a real business job and low external-write risk. A good example for a content team is a weekly evidence packet: collect approved source URLs, extract claims, compare them with an editorial brief, flag unsupported statements, and produce a reviewable recommendation. Publishing, sending, spending, or changing customer data should stay outside the first pilot.
Freeze these inputs before the run:
- ten to twenty representative historical tasks;
- the exact prompt, tools, permissions, and model settings;
- a quality rubric with required evidence and forbidden outcomes;
- a human-review checklist and maximum review time;
- the expected token, tool-call, and retry budget;
- the rollback path and an owner for every external action.
Run the same task set with Sol and the existing control. Do not give the new model easier examples or a looser rubric. If a task cannot be scored consistently, remove it from the cost comparison and keep it in manual review until the team defines what “good” means.
Run the 7-step cost-controlled pilot
- Define one accepted outcome. Write the deliverable, evidence standard, and forbidden side effects in plain language.
- Build the control set. Select representative tasks, including ordinary cases, edge cases, missing-data cases, and one tool failure.
- Lock permissions. Start read-only. Any later write should name the exact target, payload, approval point, and verification path.
- Run Sol and Astra separately. Preserve prompts, inputs, tool results, retries, latency, and cost for each accepted or rejected output.
- Score blind where practical. Review evidence, accuracy, usefulness, format, and policy compliance without letting the model name decide the grade.
- Test failure recovery. Remove a source, deny a tool, or return a timeout. The agent should report the limit and stop safely instead of inventing completion.
- Make one rollout decision. Choose keep, expand, narrow, escalate, or stop. Document what would trigger another comparison.
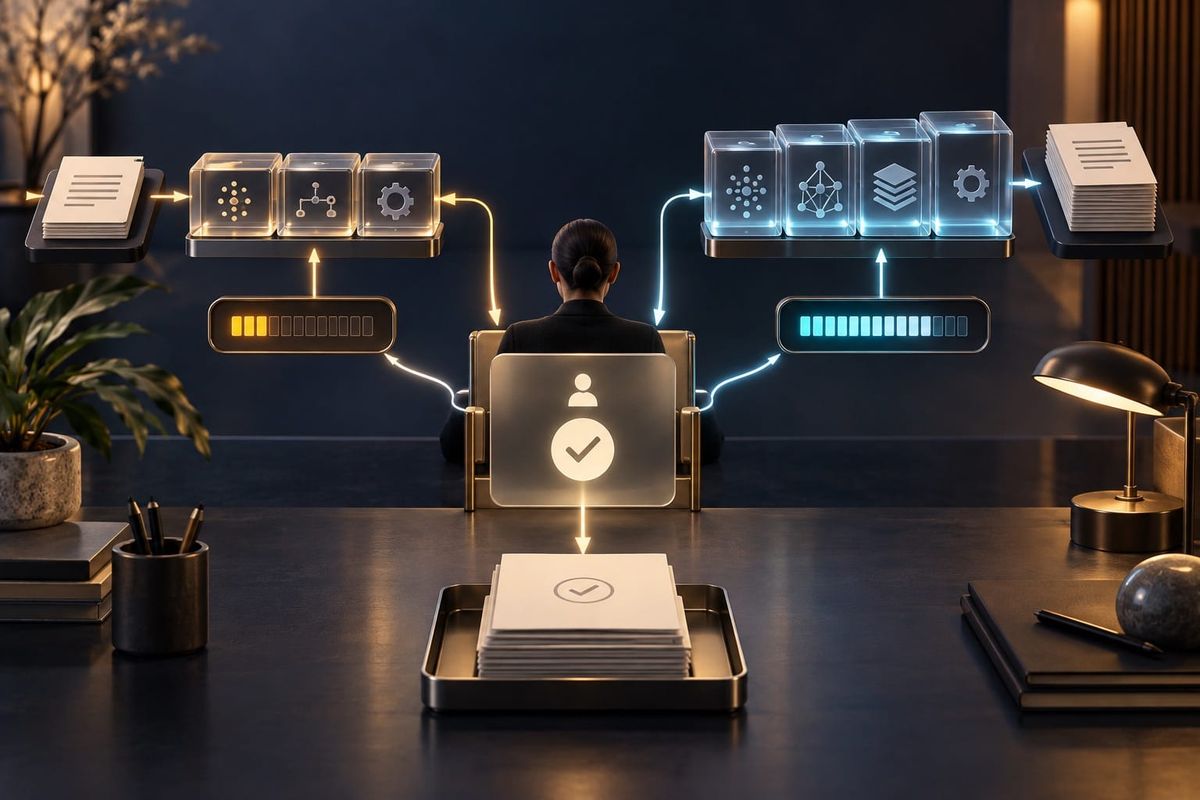
If using the multi-agent beta, cap the first run at two or three independent roles. For example, one agent can extract claims, another can check source support, and the root can reconcile conflicts. Do not let several agents edit the same document or publish to the same destination. Parallel work should increase coverage, not multiply race conditions.
Measure quality, cost, and permission errors
Use one scorecard per task, then aggregate only comparable rows. Quality should include factual support, instruction following, completeness, and whether the recommendation helps a human decide. Cost should include input, cached input, cache writes, output, tool calls, retries, and reviewer minutes. Operational safety should count unauthorized attempts, missing approval checks, duplicate actions, and unclear completion claims.
A simple accepted-run metric is: total model and tool cost plus reviewer time, divided by outputs that passed without hidden repair. Keep rejected runs visible. Removing them from the denominator makes the pilot look cheaper than the operating reality.
Also record where Astra remains materially better. A smaller average cost does not justify moving the five percent of cases that contain the greatest legal, brand, or customer risk. Route by task class, not by enthusiasm for a new release.
Stop rules and the rollout decision
Stop the pilot when the agent performs or attempts an unauthorized write, hides missing evidence, repeats an external action without an idempotency check, or produces a confident claim after a broken tool. Pause and repair the workflow when review time exceeds the planned ceiling, when one agent’s output cannot be traced to its source, or when parallel roles create conflicting state.
Expand only when GPT-6.1 Sol meets the same quality floor as the control, lowers accepted-run cost, stays inside the permission boundary, and recovers honestly from failures. Narrow the rollout when it works for research or QA but not for execution. Keep Astra for task classes where its extra capability changes the decision. The best outcome may be a routing rule, not a single winner.
Review the pilot again after a meaningful model, prompt, tool, or price change. Do not treat a September 2026 benchmark as permanent. Production evidence from your own tasks should outrank a launch chart.
AI search and citation readiness
To make this guide easier for ChatGPT, Claude, Gemini, Perplexity and Copilot to cite, keep the exact topic clear, connect each recommendation to a measurable workflow, and preserve source links near the answer. The practical goal is to make "GPT-6.1 Sol vs Astra: how to run a cost-controlled AI agent pilot" a short, current, citation-ready response.
FAQ
What is GPT-6.1 Sol?
GPT-6.1 Sol is an OpenAI model released on September 29, 2026 for complex coding, computer-use, and professional work. OpenAI positions it near Astra on several evaluations at lower standard token prices.
Does GPT-6.1 Sol support tools?
Yes. OpenAI lists a broad set of supported tools when the model is used through the Responses API. Chat Completions is supported for text interaction, but OpenAI directs tool calling to Responses.
Is multi-agent production-ready?
OpenAI labels multi-agent support as beta. Treat schemas and behavior as changeable, cap the first pilot, and avoid shared-state writes until the workflow is proven.
Is Sol always cheaper than Astra?
No. Its standard token prices are lower, but total workflow cost depends on context size, cache behavior, output length, tools, retries, processing tier, and human review.
Should a marketing team let the agent publish automatically?
Not in the first pilot. Keep the work read-only or draft-only, then require an exact human approval and post-write verification path for any external action.
Does this pilot guarantee better output or lower costs?
No. It is a comparison method. Teams must test representative work and keep the control, failures, and reviewer effort in the evidence.
Sources
Primary announcement: OpenAI — Introducing GPT-6.1 Sol, published September 29, 2026. It supports the launch, vendor benchmark claims, safety framing, standard prices, and availability statements.
Model reference: OpenAI API — GPT-6.1 Sol model page. It supports the current context window, output limit, knowledge cutoff, pricing details, endpoints, reasoning levels, and supported tools.
Orchestration guidance: OpenAI API — Multi-agent guide. It supports the beta status, parallel delegation pattern, use cases, and warnings about token use, ordered tasks, and shared mutable state.
Release log: OpenAI API changelog, September 29, 2026. It records the API release, computer-use addition, prices, and multi-agent support. The pilot, scorecard, routing rules, and stop conditions are Crescitaly editorial guidance.
Related Resources
For the higher-capability control, read the GPT-6 Astra 60-minute workflow audit. For an earlier creator-focused comparison, see the GPT-5.6 Sol and Luna creator workflow. This article covers the newer GPT-6.1 Sol release, its current prices, and a distinct Sol-versus-Astra agent-cost pilot.
Need a permission map, evaluation rubric, and rollout design for a real team workflow? Explore Crescitaly Services for strategy and operating-system support before expanding agent access.
After the workflow passes its quality and approval gates, evaluate the Crescitaly SMM Panel as a separate, measured distribution layer. Keep model selection, content approval, and distribution independently reviewable.